Findings of EMNLP 2026
DPA-MoE: A Runtime Precision Control Framework for MoE Inference
Jaeyun Kim*, Hoonki Lee*, Susie Shin, Hyunmin Kim, Dahyun Lee, Sangyeob Kim†
TL;DR Allocates precision across routed experts at runtime, so one MoE checkpoint covers a range of weight-size–quality trade-offs without retraining. To appear in Findings of EMNLP 2026.
The problem
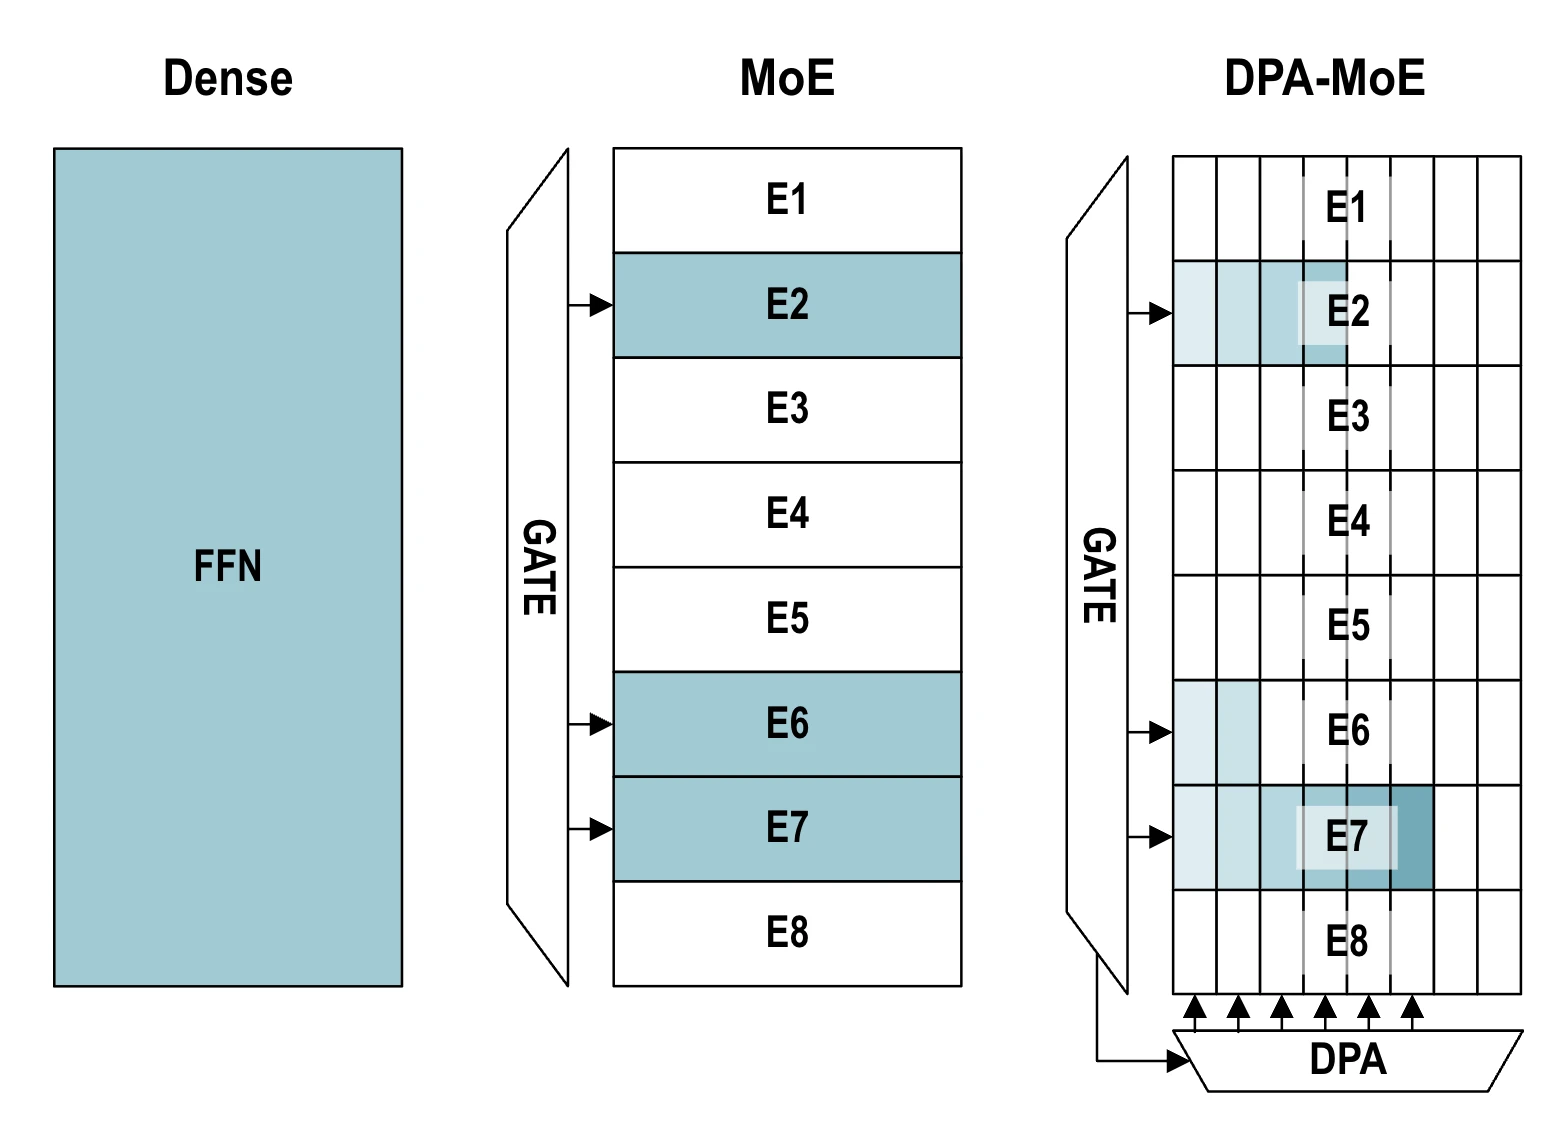
A mixture-of-experts model routes each token to a few experts, but every selected expert still runs at one fixed precision. Those experts are not equally important: they differ in gate score and in how badly quantization hurts them. A fixed-precision checkpoint also gives you exactly one memory–quality operating point.
The idea
DPA-MoE treats precision as a second decision made after routing. The router still picks which experts run; DPA then decides how many bits each of them gets.
- Prefix-decodable experts. Expert weights are encoded with SharedScale AnyBCQ into chunks, so reading more chunks gives the same expert at higher precision.
- Offline profiles. Each expert's reconstruction error at each chunk count is measured once.
- Runtime allocation. For every dispatch, live gate scores and those profiles decide which experts get more chunks, under an average budget.
The router and experts stay untouched, and one encoded checkpoint serves every budget, with no retraining or re-encoding.
Results
On Qwen3-30B-A3B and DeepSeekMoE-16B-Chat, compared with giving every expert the same precision at the same memory:
- Lower output distortion at every budget. KL divergence is up to 4.5× lower, and the same fidelity needs 2–4 GB less memory.
- Higher accuracy. It beats uniform allocation on ARC-Challenge, ARC-Easy, WinoGrande and PIQA, with the largest gains at aggressive compression.
- Modest cost. In the prototype, throughput drops 4–8% at the same budget. Because DPA reaches a given quality with fewer chunks, part of that cost comes back.
Cite & share
Citation
Jaeyun Kim*, Hoonki Lee*, Susie Shin, Hyunmin Kim, Dahyun Lee, and Sangyeob Kim†. DPA-MoE: A Runtime Precision Control Framework for MoE Inference. In Findings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP 2026). To appear. (*equal contribution, †corresponding author)
@inproceedings{kim2026dpamoe,
  title     = {{DPA}-MoE: A Runtime Precision Control Framework for {M}o{E} Inference},
  author    = {Kim, Jaeyun and Lee, Hoonki and Shin, Susie and Kim, Hyunmin and
               Lee, Dahyun and Kim, Sangyeob},
  booktitle = {Findings of the 2026 Conference on Empirical Methods in Natural Language Processing},
  year      = {2026},
  url       = {https://openreview.net/forum?id=BrcO2Gg9A9}
}